
Sigmoid, tanh, ReLU functions. What are they and when to use which?

If you are working on Deep Learning or Machine Learning in general, you have heard of these three functions quite frequently. We know that they can all be used as activation functions in neural networks. But what are these functions and why do people use for example ReLU in this part, sigmoid in another part and so on? Here is a friendly introduction to these functions and a brief explanation of when to use which.
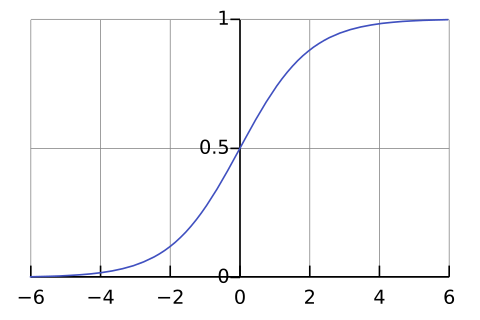
Sigmoid function


  • Output from 0 to 1
  • Exponential computation (hence, slow)
  • Is usually used for binary classification (when output is 0 or 1)
  • Almost never used (e.g., tanh is a better option)

Tanh function


  • A rescaled logistic sigmoid function (center at 0)
  • Exponential computation
  • Works better than sigmoid

ReLU function (Rectified Linear Unit) and its variants


  • Faster to compute
  • Often used as default for activation function in hidden layers

ReLU is a simple model which gives 0 value to all W*x + b < 0. The importance is that it introduces to our network the non-linearity, which is important for activations.


Comments

Popular posts from this blog

Quick text files merging, data preparation

It's very often that in natural language processing, you will have to re-format your data to take as inputs to different systems. In this case, these simple linux commands will help you do it much quicker without having to write a script. 1. Merging two files to one file with two column Input f1 looks like this: 1 2 3 4 Input f2 looks like this: a b c d Output f3 will look like this: 1  a 2  b 3  c 4  d Command: paste f1 f2 > f3  The delimiter by default is a tab. You can also define it (for example, separated by a comma) as follows: paste -d ',' f1 f2 > f3 2.  Create a line number to each line of a text file Assume that you want to create an index to each line in a text file, i.e. inserting a line number and then a tab before the content of each line: Input f1: a b c d Output f2: 1  a 2  b 3  c 4  d Command: nl f1 > f2 3. Joining two files with a common field Input f1: 1   aaa...

Skip-gram model and negative sampling

In the previous post , we have seen the 3 word2vec models: skip-gram, CBOW and GloVe. Now let's have a look at negative sampling and what it is used to make training skip-gram faster. The idea is originated from this paper: " Distributed Representations of Words and Phrases and their Compositionality ” (Mikolov et al. 2013) In the previous example , we have seen that if we have a vocabulary of size 10K, and we want to train word vectors of size 300. Then the number of parameters we have to estimate in each layer is 10Kx300. This number is big and makes training prone to over-fitting and gives too much focus on words that appear often, and less focus on rare words. Subsampling of frequent words So the idea of subsampling is that: we try to maximize the probability that "real outside word" appears, and minimize the probability that "random words" appear around center word. Real outside words are words that characterize the meaning of the center word, wh...